Public research uploads are available. Use HTTPS to build, export and reuse models online. Submit only authorized, non-sensitive research data. De-identified molecular data can remain sensitive. The service retains unsupported Python 3.7/Django 2.1; use a controlled deployment where confidentiality or specific erasure requirements apply. Read the data handling and retention policy before uploading.

Step 1: Please select an analysis task.

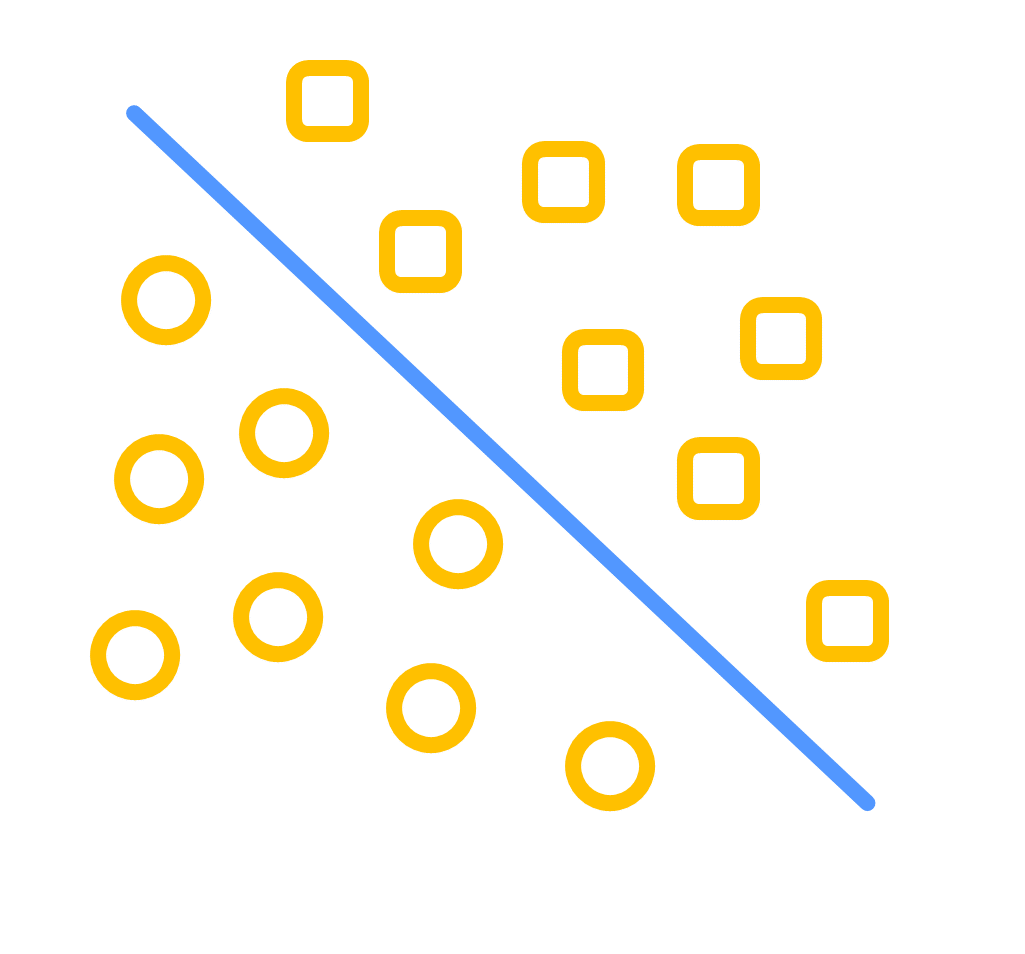
Binary classification

The process of dividing new observations into distinct two categories based on the features of a set of input data.

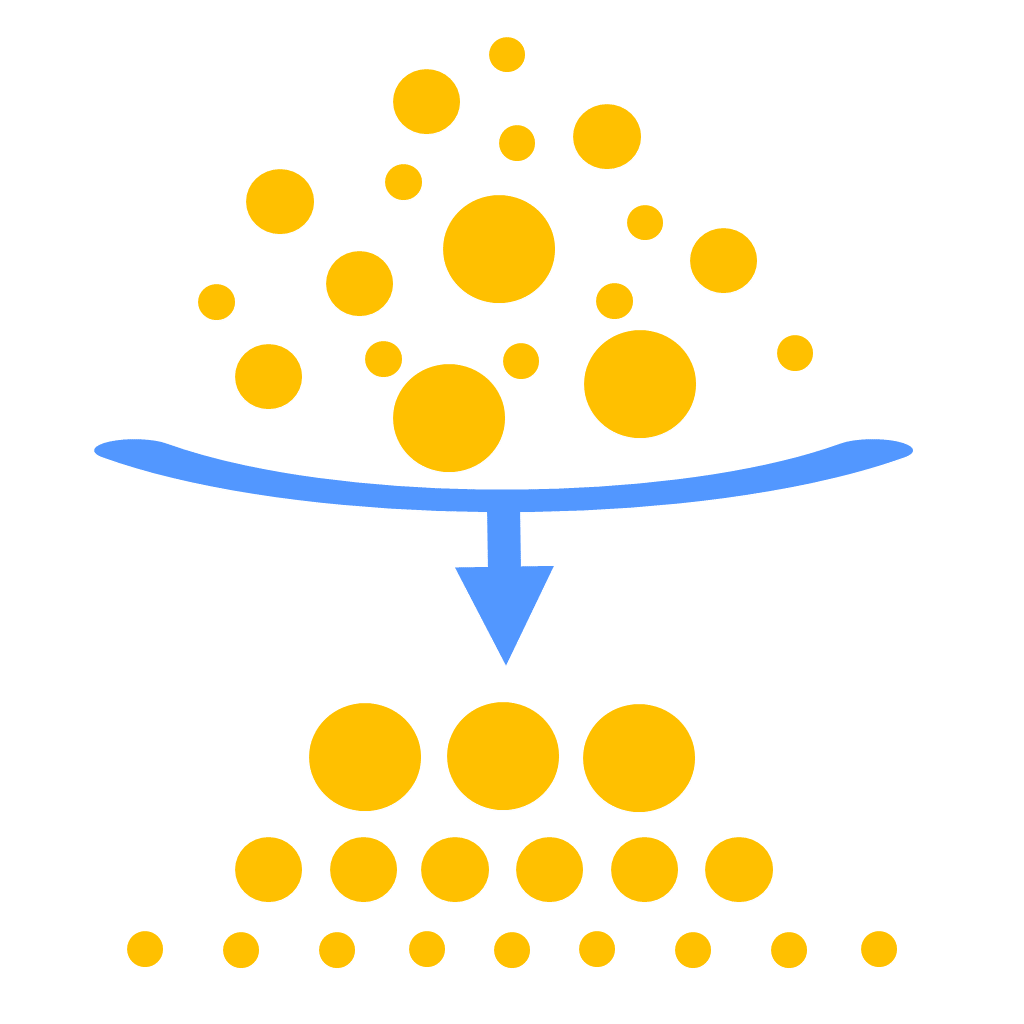
Multiclass classification

The process of dividing new observations into distinct at least three categories based on the features of a set of input data.

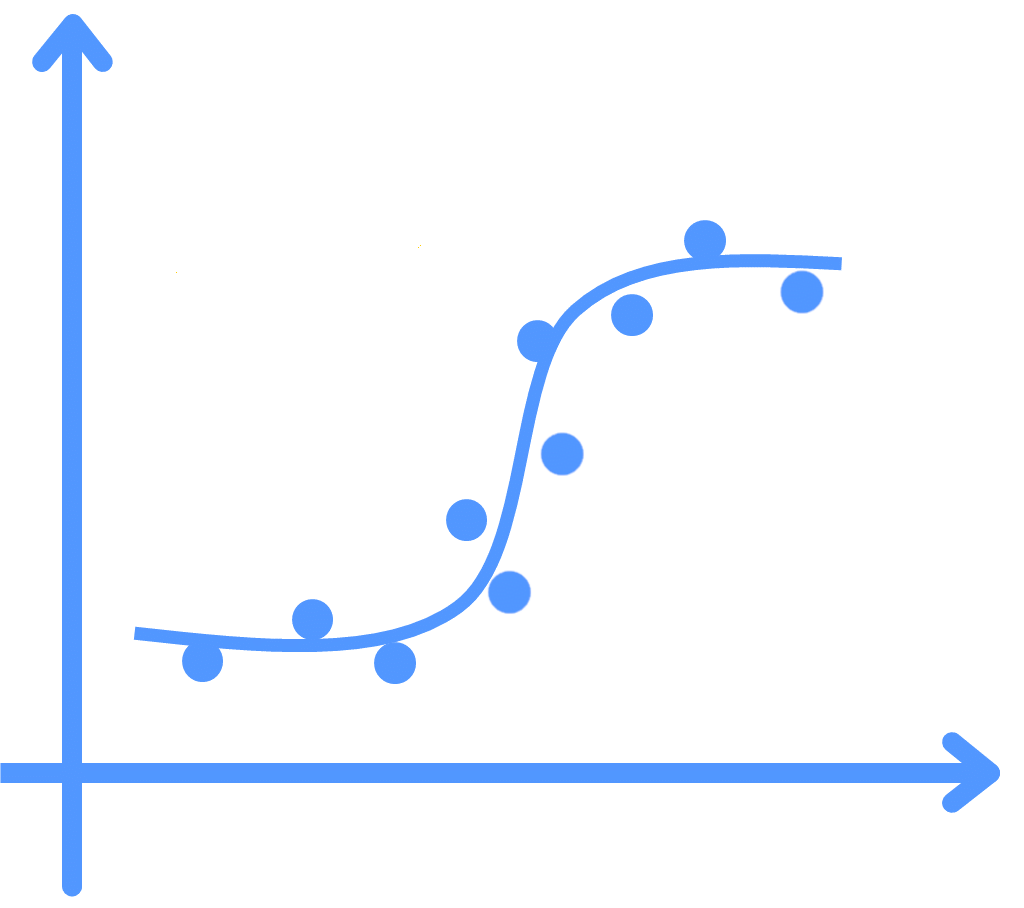
Regression

The process of exploring the relationships between dependent variables (labels) and a series of indenpendent variables (features).

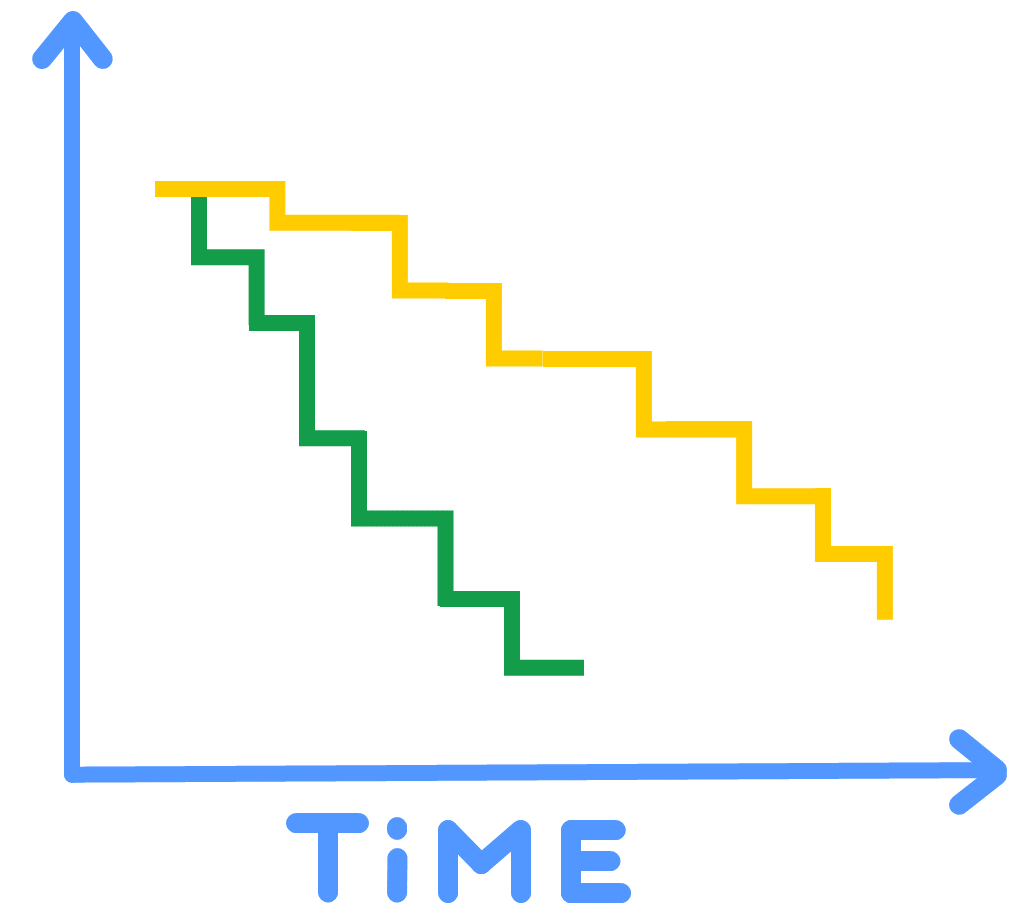
Survival

The process of establishing the connection between covariates (features) and the time of events (labels) to predict the risk of future events.


Step 2: Please upload the data file.


File: 


File: Upload a CSV file with features in rows and samples in columns. The file must be no larger than 50 MiB. Example/template files are provided to illustrate the required input format.

Template: Classification and regression files use the first three rows for sample name, label, and train/test set. Survival files use the first four rows for sample name, status, time, and train/test set. Example files can be downloaded below.

Patient-level safeguard: TCGA-style barcodes are grouped by patient at analysis time. Patients found in both training and testing are excluded from both; repeated aliquots within one partition are reduced by a fixed sample-type/vial rule. The public result contains counts only; the private project audit retains barcode details until deletion. Analyzed sample counts may be lower than the preview.

Repeated observations: Add a row named subject_id immediately after the set row when samples share a patient, family or site. The ID is excluded from predictors. Supported TopK/MRMR/PCA/no-reduction paths keep subjects disjoint in inner and outer CV. Grouped FSS/BSS requests are rejected because their internal selection is not group-aware. If omitted, CV assumes independent samples. Optional cohort_provenance documents origin; naming a set external alone does not establish independence.

Project access: MALER generates a random project suffix and a separate access token. Keep the result link private; the project ID alone is not sufficient to retrieve data or results.

Privacy: Upload only authorized, non-sensitive research data. Do not upload direct identifiers, confidential records or sensitive patient data. De-identification alone does not remove all sensitivity. Access expires after 24 hours; scheduled cleanup removes active task files separately. Other copies are outside this deletion guarantee. Read the data handling and retention policy. Data upload limit: 50 MiB.


Step 3: Please select a feature scaling method. (Optional)


Z-Score is the recommended default for fair comparison of scale-sensitive SVM, KNN and penalized linear models. Tree-based models are generally less scale sensitive. The setting can be changed, including to no scaling; doing so for a scale-sensitive model may make comparisons unfair. Scaling is fitted inside every training fold, and the selected setting is recorded with the result.


Step 4: Please select feature ranking and subset search methods.


ANOVA is suitable for fast univariate ranking in classification or regression tasks. MRMR considers relevance and redundancy and is useful when many correlated features are expected. Cox ranking is used for survival analysis.


TopK tunes the retained feature count. FSS and BSS use task-specific sequential selection after a fold-local prescreen capped at 50 candidates. Their additional internal scores reuse enclosing-fold preprocessing. Grouped FSS/BSS and binary FSS/BSS with an explicit probability cutoff are unavailable. PCA is unsupervised and returns components rather than a gene signature. Preprocessing and selection are refit within each model-search training fold.


Step 5: Please choose an analysis strategy.


Naive Bayes

A kind of simple probabilistic classification model based on Bayes’ theorem with the assumption of independence between features.

SVM

SVM aims to create a decision boundary called maximum margin separating hyperplane that enables the prediction of labels from one or more features.

RandomForest

An ensemble estimator that fits a number of decision tree classifiers on various sub-samples of the dataset

Logistic

Logistic regression adds a nonlinear function to a linear function to estimate the probability of an event occurring.

KNN

A non-parametric method which assigns the samples with labels by the majority rule on the labels of selected nearest neighbors.

XGBoost

A scalable and highly accurate implementation of gradient boosting which integrates multiple parallel tree models to build a more powerful learner model.

lightGBM

A gradient boosting framework that uses tree based learning algorithms.it uses histogram-based algorithms to speed up training and reduce memory usage.

Adaboost

An ensemble estimator based on multiple weak prediction models.It can adjust the weight of misclassified instances so that subsequent classifiers focus more on difficult cases.

DecisionTree

A non-parametric algorithm that can classify a population into branch-like segments that construct an inverted tree with a root node, internal nodes, and leaf nodes.

GBDT

An ensemble estimator based on multiple decision trees models. It will fit a decision tree on the residuals error of the previous tree.

LinearRegression

It establishes a linear relationship between label and features to minimize the residual sum of squares between the observed targets and the predicted targets.

SVM

It aims to create a decision boundary called maximum margin separating hyperplane such that all data in a set are at the shortest distance from the hyperplane

Ridge

A linear regression model where the loss function is the linear least squares function and regularization is given by the l2-norm.

Lasso

a linear regression model that minimizes the residual sum of squares so it tends to produce some coefficients that are exactly 0 and hence gives interpretable models.

DecisionTree

A non-parametric model that predicts the values of target variables by learning simple decision rules inferred from data features.

XGBoost

A scalable and highly accurate implementation of gradient boosting which integrates multiple parallel tree models to build a more powerful learner model.

RandomForest

An ensemble estimator that fits a number of decision tree classifiers on various sub-samples of the dataset

Adaboost

An ensemble estimator based on multiple weak prediction models.It can adjust the weight of misclassified instances so that subsequent classifiers focus more on difficult cases.

GradientBoost

An ensemble estimator based on multiple decision trees models. It will fit a decision tree on the residuals error of the previous tree.

SurvivalSVM

Support vector machine (SVM) method is used for survival analysis.

SurvivalTree

SurvivalTree method is used for survival analysis.

ExtraSurvivalTrees

An ensemble estimator that fits a number of randomized survival trees on various sub-samples of the dataset.

RandomSurvivalForest

An ensemble estimator that fits a number of survivaltrees on various sub-samples of the dataset.

GradientBoostingSurvival

Gradient-boosted Cox proportional hazard loss with regression trees as base learner.


One-Click Analysis: Each requested estimator family is tuned and evaluated on development data. A family is selected from these development summaries, finally tuned/refitted on development data, and its full configuration is locked before held-out scoring. The winning development mean can be optimistic for this selection procedure.

Customized Analysis: Users can choose to specify models and parameters to personalize the data.

Validation budget: The web default is 5 outer folds × 2 repeats with 3 inner folds. The manuscript's fixed-family validation scripts use 5 outer folds × 10 repeats with 3 inner folds; the web default does not reproduce that computational effort. Grouped regression uses one distinct outer repeat because GroupKFold is deterministic. The result records requested and actual budgets, actual distinct repeats, and each candidate grid/count. Infeasible folds produce an error or a recorded reduction.

Complete parameter record: All estimator classes, defaults, scaling requirements and searched values are available in the versioned machine-readable method registry.


Step 6: Email (Optional)


If server SMTP is configured, MALER can send the private result link to this address after completion. The result is also returned directly in the browser; email is never required.


Please access your task status or results via this link